 SHEYU.AI
Robots.txt is becoming a commercial file for negotiating with AI companies
For Chinese teams selling abroad, robots.txt is shifting from a technical file for search engines into a commercial one for setting terms with AI firms.
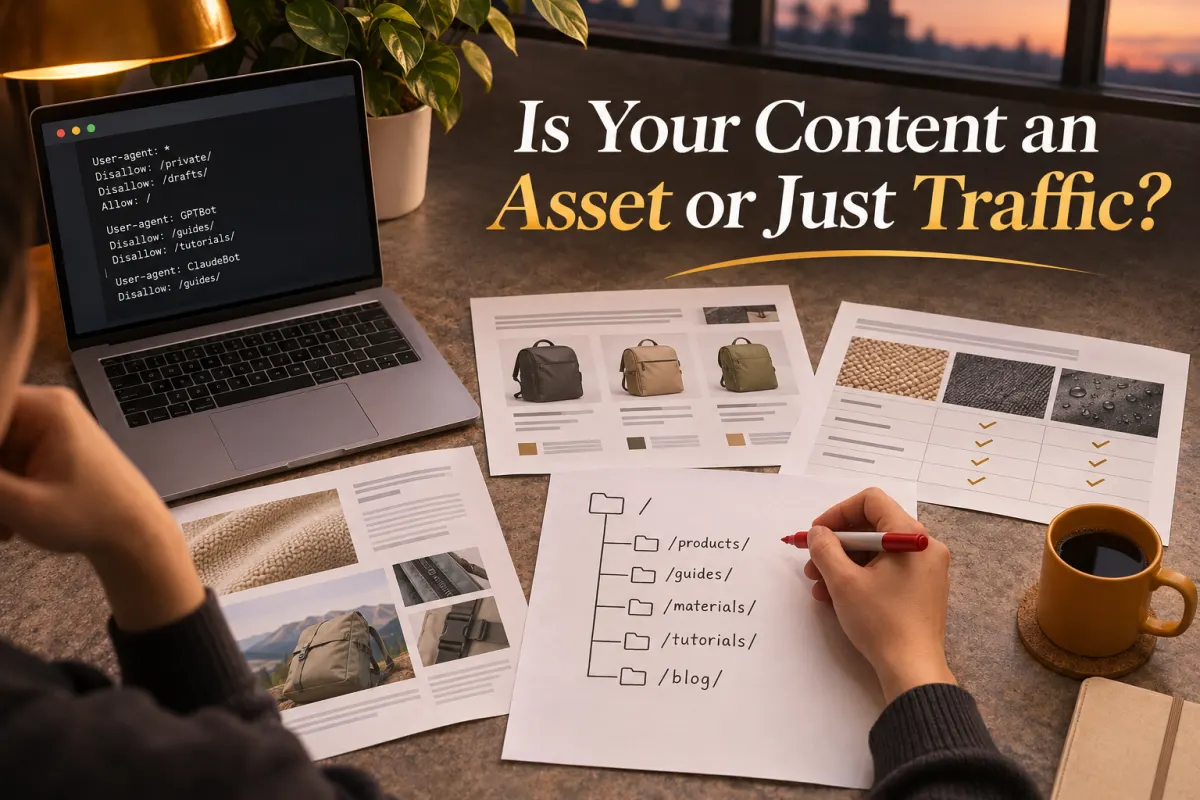
For content publishers, the days of declaring their terms one company at a time may be ending. For teams going global and small businesses, the implication is a single judgment: robots.txt is turning from a technical file read by search engines into a commercial file for negotiating with AI companies.
Why this matters to a site that sells goods
robots.txt is an old mechanism. It was designed to tell crawlers what they may and may not fetch, and search indexing, web archiving and AI training all rely on it. The problem is that every AI company now wants its own declaration, forcing sites to state their position repeatedly while AI crawlers keep fetching.
The most common objection: I don't make money from content, so let them crawl
That argument has some merit for pure e-commerce standalone sites. When product and price pages are fetched by AI, it is arguably free exposure.
But it comes with a precondition: you first have to work out which parts of your site you want crawled and which you do not.
Take a hypothetical case: a team running a DTC business abroad has a website with product pages plus a full set of original selection guides, material comparisons and usage tutorials. They paid people to write this material, and it drives search rankings and conversion. If AI companies scrape it for training and a user then asks an AI directly which of two materials is better, the AI answers and the user never visits your site. What you wrote becomes someone else's answer bank.
So the real question is not whether crawling happens, but whether you have stated a position. With no stated position, the default is open.
When this judgment does not hold
The boundaries need to be clear.
First, if your site is almost entirely product listings and prices, with no original content assets, this is genuinely not a high priority. Editing robots.txt is technical maintenance for you, not a business decision.
Second, if most of your traffic comes from within platforms (Amazon or TikTok Shop, for example) and the standalone site is only a display page, the impact is limited.
Conversely, if you meet these conditions — you have a standalone site, you have original content, that content is itself a customer-acquisition asset, and your team is going global — this deserves a place on this week's to-do list.
Half a step ahead: one thing you can do now
Open your site's robots.txt and take a look.
There is no need to rush to change it. First see clearly what is written there, whether there are any declarations aimed at AI crawlers, and who those declarations are meant for.
Once you see that clearly, decide which directories to open and which to close. The action itself is not complicated; the judgment is — you first need to know where your content assets lie.
Back to robots.txt. The real value of this is not technical. It forces you to answer a question: is your content an asset or just traffic?
Once that is clear, whether and how to change the file are secondary matters.